The blog.
8 posts on benchmarksRSS feed
Haiku 5.5 vs GPT-6 Luna: The Benchmarks Lied
Anthropic's benchmarks said Haiku 5.5 crushes OpenAI's GPT-6 Luna. I ran them head-to-head on the same prompts and harness — and the real-world results told a completely different story.
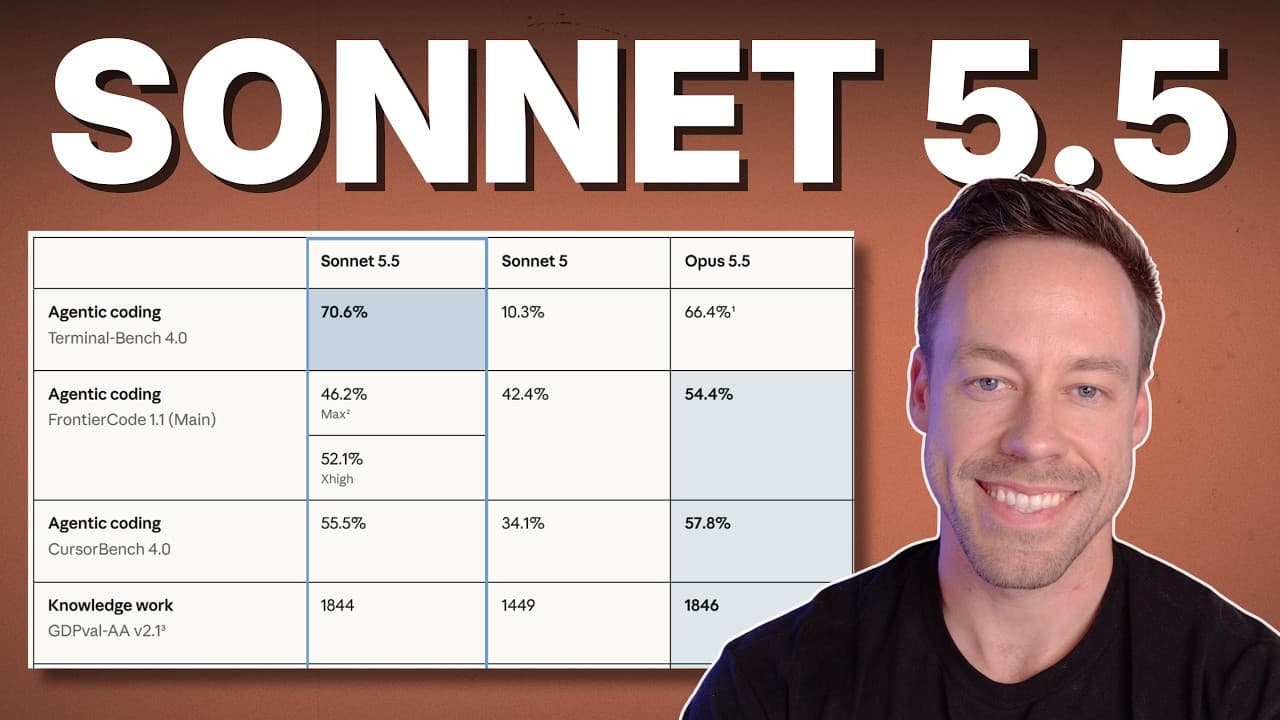
Claude Sonnet 5.5: Beats Opus at Coding, Half the Cost
Claude Sonnet 5.5 is 30% faster, 30% cheaper, and on one agentic coding benchmark it actually edges out Opus 5.5. Here's what the numbers mean for your day-to-day work.
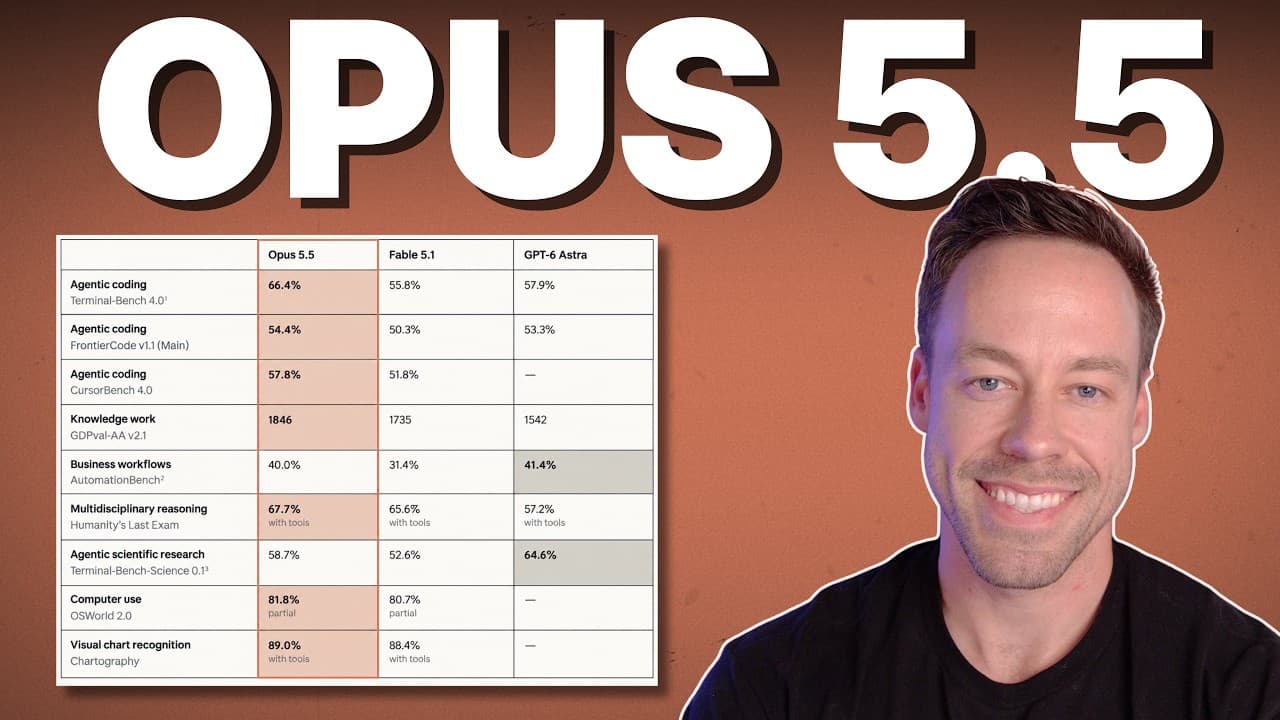
Claude Opus 5.5: Fable 5.1 Performance at 40% Less
Claude Opus 5.5 matches Fable 5.1 performance at about 40% less cost. Here are the benchmarks, per-task pricing, and which effort level to actually use.
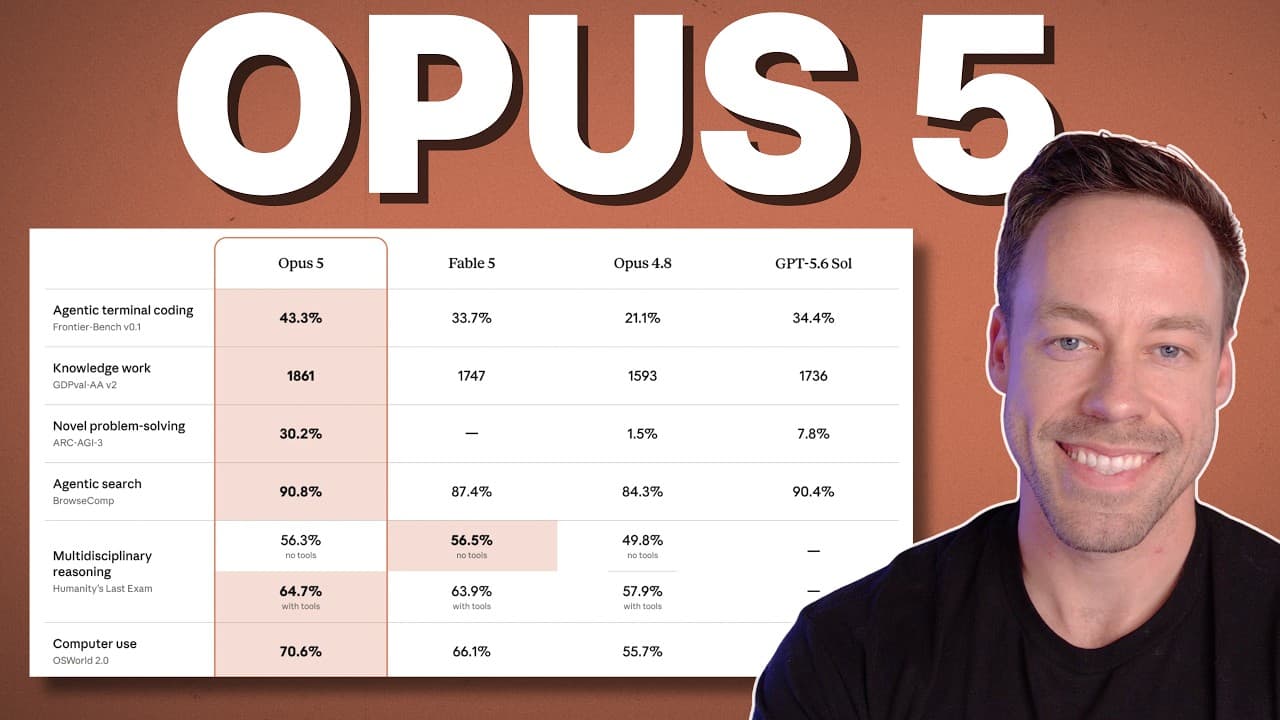
Claude Opus 5 Benchmarks: Fable 5 Performance at Half the Cost
Claude Opus 5 matches Fable 5 on most benchmarks at half the cost, plus a massive jump over Opus 4.8. Here is what actually matters in the release.
DeepSeek V4 vs Opus 4.7 vs GPT 5.5: Which Coding Agent Wins?
I tested Opus 4.7, GPT 5.5, and DeepSeek V4 head-to-head on a flight simulator and a WebGPU landing page. Here is which one actually wins.
Claude Opus 4.7 Benchmarks: What Actually Changed in 2026
Anthropic just dropped Claude Opus 4.7. The benchmarks show a real jump in coding, vision, and document reasoning. Here's what matters and what it costs.
Did Claude's 1M Context Window Defeat Context Rot?
Opus 4.6's 1M token context window scores 78.3% on the eight-needle test with only a 14% drop from 256K tokens. Here's what the benchmark data actually means.
Gemini 3.1 Pro vs Opus 4.6 and GPT-5.2: Benchmarks
Google dropped Gemini 3.1 Pro and it's legitimately competing with Opus 4.6 and GPT-5.2 — often at a lower price. Here's what the benchmarks actually mean and whether you should switch.